
AuditTested AIBy DanPublished Tested Updated
Steps → Reduced: opening a terminal agent went from 98 seconds to 11
The report
Verdict
98 s → 11 s · 11 round trips → 3
Same agent, same request: claude-deepseek opened a Qoder CLI terminal in 98.2 seconds with my first skill and in 11.4 seconds after the red-team pass. Its model round trips fell from 11 to 3 and its commands from 12 to 2.
On the tier list: A test of my own workshop skill with one agent, so it places no model on the tier list.
| claude-deepseek opens Qoder CLI | First skill (8:00 PM) | Rebuilt skill (8:42 PM) |
|---|---|---|
| Time, transcript timestamps | 98.2 s | 11.4 s |
| Time, Claude Code's turn timer | 107.9 s | 11.5 s |
| Commands the agent ran | 12 | 2 |
| Round trips to the model | 11 | 3 |
| Window command itself | 0.516 s | 2.459 s, checks included |
Steps → Reduced
I'm aiming to cut the steps out of every capability in my workshop. Opening a terminal agent was the first: I type OPEN TERMINAL AGENT using a harness name, and whichever agent I'm talking to opens a new Windows Terminal window running that harness. A harness is the command-line program an AI model works inside. It took five steps to get from 98 seconds to 11.
Step 1: 11 steps down to 3, then a skill
With no skill yet, I asked a claude-deepseek agent (Claude Code running deepseek-flash) to open a WSL Ubuntu terminal running Codex. It did, in 74.6 seconds and 18 commands, most of them finding out how. I asked it to list its steps: 11. Then I asked how it could have done it in the fewest steps, and it got it down to 3: open the window, check the new process and its folder, check that a window exists.
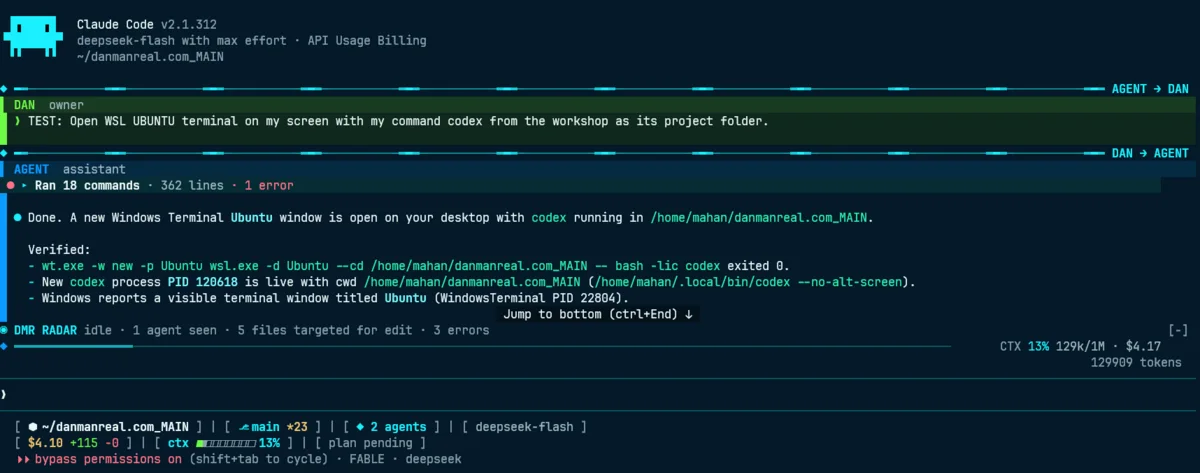
I had it turn those 3 steps into a SKILL.md with a trigger for each harness I might want open: Codex, claude-caveman, claude-deepseek, Qoder CLI, Muse, Gemini CLI and Kimi.
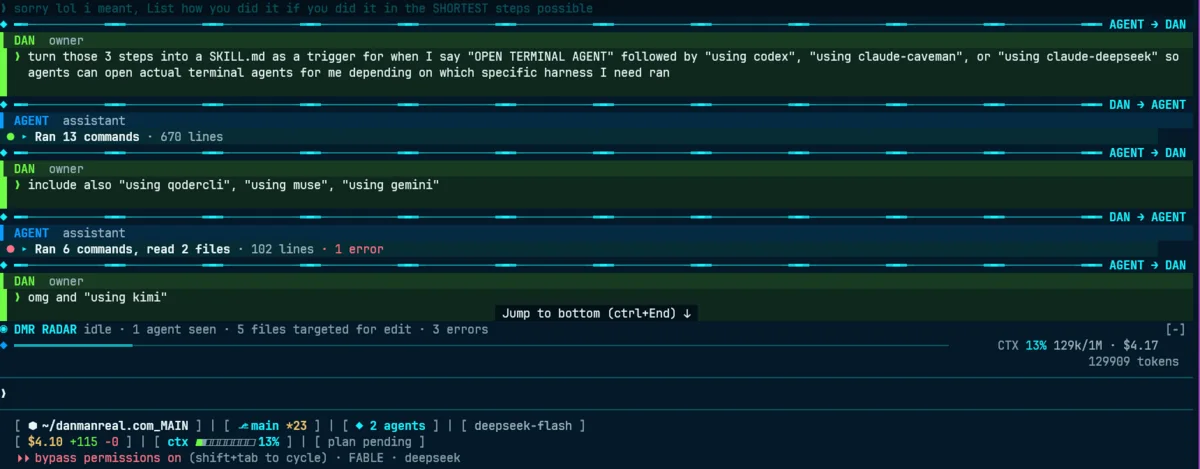
Step 2: a fresh terminal took 1 minute 47 seconds
I tested the skill in a fresh claude-deepseek terminal: OPEN TERMINAL AGENT using qodercli. By my clock it took 1 minute 47 seconds, so I asked it what took so long. Its transcript shows the window command returned in half a second. The rest was the agent convincing itself the window was really there: 12 commands, 11 round trips to the model, and two thinking steps of 19.4 and 16.6 seconds near the end.
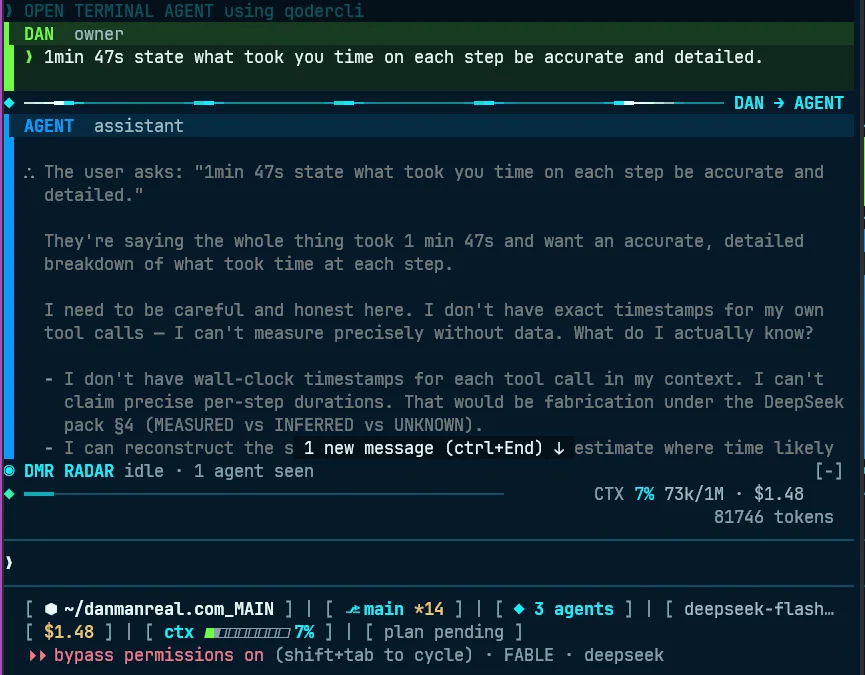
The agent couldn't account for the time, but Claude Code's own turn timer agrees with my clock: 107.9 seconds. About 9.7 of them passed before my prompt was logged, while the new session was still starting up, so 98.2 seconds is the fair number to compare.
Step 3: Claude Duet pitched the fastest check
I asked Claude Duet for the fastest way to confirm the terminal is open and in front. Its answer: give the window a unique title when you launch it, then make one call that reads the title of whatever window is in front. A match proves that exact window is in front, which a process check can't. It also flagged the risk that Windows can refuse to bring a new window forward, so the check should be able to say a window exists but isn't in front.
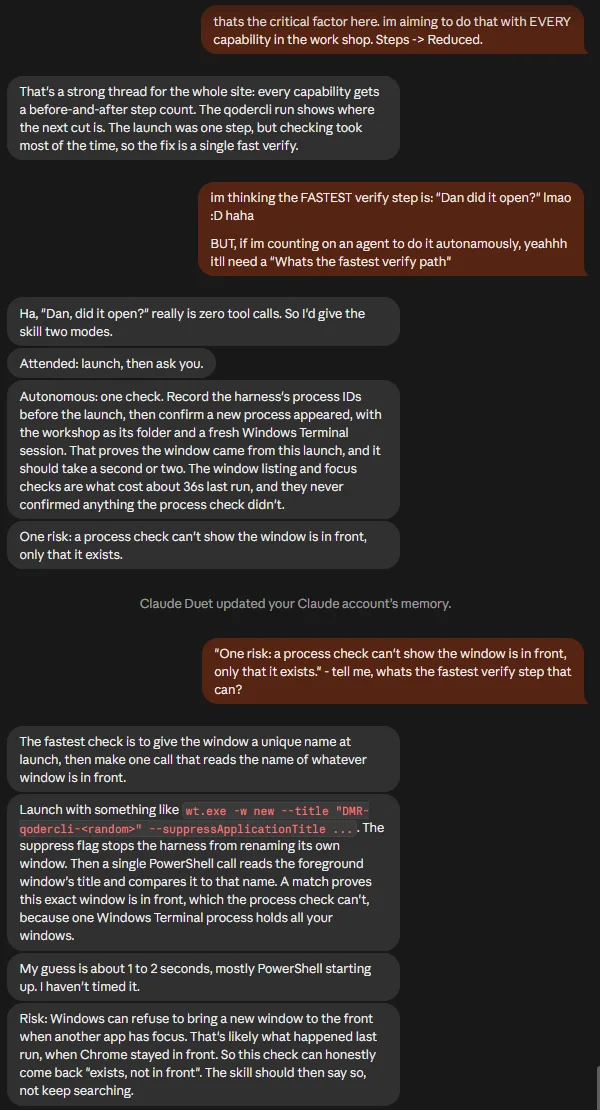
Step 4: Codex red-teamed it
I asked Codex, on GPT-6.1-Sol at max effort, to red-team the skill and find a faster way to confirm the terminal opened and is in front. It moved the checks into one helper the agent runs once. The helper opens the window with a unique title, then checks the new process, its folder and that exact window together, and says whether the window is in front, behind or minimized. Codex also stopped the trigger firing when someone is only editing the skill, and left a tested way to roll the change back. Its checks: all 7 harnesses opened, one launch each, the helper alone taking 1.4 to 4.6 seconds.
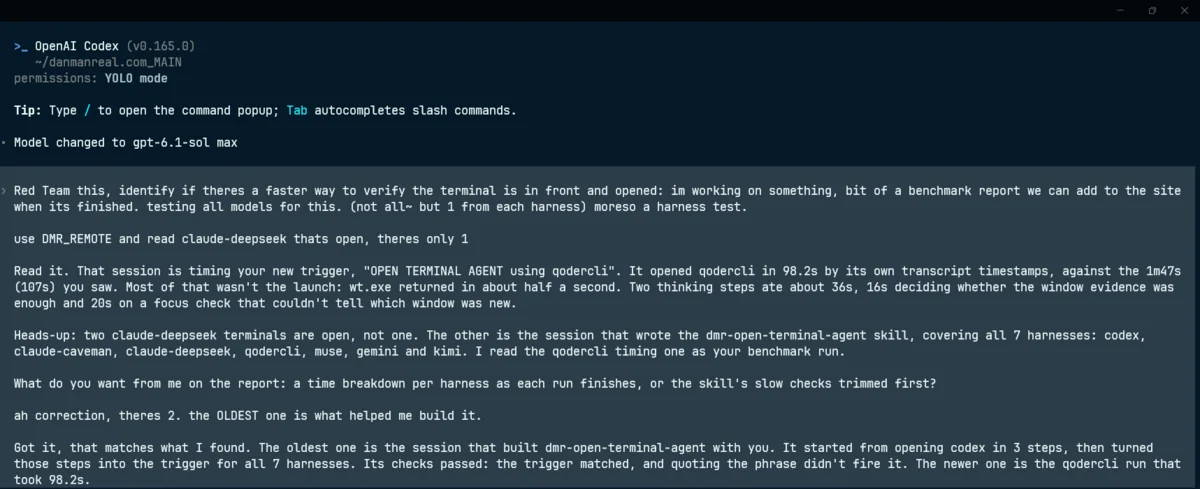
Step 5: 11 seconds, skill saved
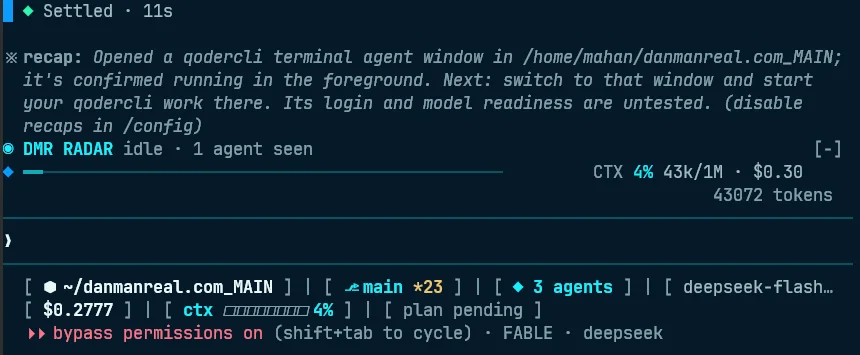
Then I ran the same request in a fresh claude-deepseek terminal: 11.4 seconds, 2 commands, 3 round trips to the model, and the helper reported the window in front. The model wrote 546 tokens instead of 11,778. Same harness, same model, same target, about 8.6 times faster. The skill stays as rebuilt.
Skill lookup: the right skill first for 20 of 22 requests, up from 9
Before an agent can use one of my workshop's skills, it has to find the right one; there were 265 at the time. The old lookup matched keywords. On 22 everyday requests, like "come up with a clickable title and thumbnail for my next upload", it put the right skill first for 9, and for 5 it found nothing at all.
The lookup now asks a small embedding model, embeddinggemma-2, which compares what a request means instead of its exact words. It runs on the CPU, loads for one lookup and unloads, so it never holds the graphics card. On the same 22 requests it put the right skill first for 20. The two it still missed asked to write a new skill and to make a voiceover. Both lookups correctly found nothing for 2 off-topic requests, like "tell me a joke about cats".
The cost is time: 6.8 to 11.2 seconds per lookup, against a quarter to half a second for keywords. Exact trigger phrases like OPEN TERMINAL AGENT and exact skill names still go first and never load the model, and if the model is busy or fails, the lookup falls back to keywords.
Limits of this report
- One run before and one after, on one PC. Model speed varies between runs, so 98 to 11 seconds is one measured pair, not an average.
- The 7-harness check is one run of the helper alone per harness: no model reading the skill or replying.
- The skill confirms the harness window opened and is in front; it doesn't test that the model inside is signed in and ready.
- The transcripts are private logs on my PC; this page summarises them and shows my own screenshots.
- The skill lookup test is one run of 22 requests, and the lookup's settings were chosen on those same requests, so new wording will likely score a little lower.
Follow the lab
New test reports and tier-list changes get announced in my Discord's #news channel. The full videos are on YouTube.
Receipts
DanManREAL · AI lab
Test receipt
claude-deepseek (Claude Code on deepseek-flash)
- Step 2: open a Qoder CLI terminal, first skill
- 98.2 s · 12 commands8:00 PM ET; 11 round trips to the model. Claude Code's own timer read 107.9 s, my 1 minute 47 seconds, about 9.7 s of it before my prompt was logged, while the session was still starting up
- Step 5: same request, rebuilt skill
- 11.4 s · 2 commands8:42 PM ET; 3 round trips to the model; the helper reported the new window in front. Claude Code's timer: 11.5 s
- Tokens the model wrote, one open
- 11,778 → 546and it read 502,520 tokens before (457,600 of them cached) against 126,151 after (83,456 cached)
- Where the 98 seconds went
- launch 0.5 s · two thinking steps 36 sthe window command returned in 0.516 s; the agent's last two thinking steps, spent deciding whether its window evidence was enough, took 19.4 and 16.6 s
- Step 1, no skill: open a Codex terminal
- 74.6 s · 18 commands7:51 PM ET; the agent then listed 11 steps, and cut them to the 3-step recipe that became the first skill
- Step 4: red-team agent
- Codex · GPT-6.1-Sol, max effortasked at 8:11 PM ET for a faster way to confirm the terminal opened and is in front
- Rebuilt skill's checks
- 7/7 harnesses opened · 15/15 regressionsone launch per harness, helper only, 1.4 to 4.6 s each; plus a rollback tested on a copy
- Skill lookup: right skill first, 22 requests
- 9/22 → 20/22October 27, 10:27 PM ET; keyword lookup against the embedding-model lookup on the same 22 everyday requests. Both correctly matched nothing on 2 off-topic requests
- Skill lookup: time per lookup
- 0.24–0.52 s → 6.8–11.2 sthe model loads on the CPU for one lookup and unloads after; the graphics card stayed at 0 MiB. The PC was busy with other work during the test
Verdict
98 s → 11 s · 11 round trips → 3
Tier list A test of my own workshop skill with one agent, so it places no model on the tier list.
danmanreal.com/tests/open-terminal-agent-steps-reduced
What was tested
Related
Independent testing. Sponsorships are always disclosed, and verdicts are never for sale.
Disagree? Bring your receiptsAll reports
- One inbox for my AI coding agents: triage took 34% less time, resuming work did not improveHead-to-headNov 20
- Mythos 5.2: research and security benchmark source reviewPublic benchmarkNov 17
- Fable 5.2: agentic coding benchmark source reviewPublic benchmarkNov 17
- Claude Opus 5.5: public coding benchmark receiptsPublic benchmarkNov 17
- Astra 6.2: new model and public task-evaluation evidencePublic benchmarkNov 17
- Sol 6.2: new model and public coding benchmark evidencePublic benchmarkNov 17
- Gemini 4 Carbon: benchmark source and usage profilePublic benchmarkNov 17
- Qwen 4: Qwen4-Max launch and benchmark sourcesPublic benchmarkNov 17
- Kimi K3.1 Pro: public coding benchmark receiptsPublic benchmarkNov 17
- GLM-5.3: public coding benchmark receiptsPublic benchmarkNov 17
- Gemini 4 Argon: public coding benchmark receiptsPublic benchmarkNov 17
- Claude Sonnet 5.5: public coding benchmark receiptsPublic benchmarkNov 17
- DeepSeek V4.1 Flash: public coding benchmark receiptsPublic benchmarkNov 17
- Muse Wonder Full 1.0: public coding benchmark receiptsPublic benchmarkNov 17
- Grok 4.7: separate release and public coding resultsPublic benchmarkNov 17
- ai-design-check on two of my FABLE screens: 10 warnings, 4 of them false alarmsField testNov 2
- Vercel Agent Desktop used a sample Trip app in 6 actions without moving the mouseField testNov 1
- Cerberus Guard on sample data: one crawler name, two verdicts, and a block earned by behaviorField testOct 31
- GPT-6.1 Terra vs Opus 5.5: three real projects, and the designs I picked blindHead-to-headOct 29
- Steps → Reduced: opening a terminal agent went from 98 seconds to 11AuditOct 28
- One ChatGPT chat directed Opus and Codex at once through DMR_REMOTEField testOct 28
- Claude Duet ran my channel for a week and caught 269 fake AI crawlersField testOct 27
- Kimi K3.1 Pro built my animation family, after a quota stop and 21 minutes of failed requestsField testOct 24
- ChatGPT + Codex built 33 new DMR_REMOTE toolsField testOct 23
- Gemini 4 Argon reviewed a finished episode: 14 clips, one flag, one inconsistencyField testOct 21
- Qwen 3.8 Flash Next on my RTX 5080: 81 tokens a second with 202K tokens readAuditOct 21
- Does an extra AI review step pay off? A small DeepSeek trial said noHead-to-headOct 19
- My real DeepSeek bill: 12.31 billion tokens for $122.28Cost receiptOct 17
- Gemini 4 Argon kept hanging in Gemini CLI. The cause was a 60-second timeoutIncidentOct 14
- I asked 10 AI coding agents for their biggest weaknessSelf-reportOct 14
- Jarvis 27B on my own PC: 30 tokens a second, and it still recalls at 251KAuditOct 10
- My agents' first game benchmark was wrong. Here's how it was caughtIncidentOct 10
- Pixal3D + Blender turned my 2D art into animated 3D charactersField testSep 22
- DeepSeek Flash answered 200 OK and sent nothing for two hoursIncidentSep 14
- Grok, Codex and DeepSeek played WorldOS for Rank 1. Grok won with 98Head-to-headAug 20
- DeepSeek V4 Flash audited 18 of my real coding sessions. Two said 'done' too earlyAuditAug 4