
Field testTested AIBy DanPublished Tested Updated
One ChatGPT chat directed Opus and Codex at once through DMR_REMOTE
The report
Verdict
Two agents, one chat, no pause
Mid-review of Opus's work, ChatGPT launched a Codex terminal to ship a DMR_REMOTE repair, then passed Opus's install eight minutes later. Recorded OpenAI connector activity rose during the launch. DMR_REMOTE's own logs back the counts; they do not isolate one chat's call rate.
On the tier list: A record of agents working together through my own tool on one afternoon, so it places no agent on the tier list.
What was happening
On October 28 one ChatGPT chat was reviewing Opus's work on DMR_NOW_LOG, my log-review project: Opus builds a change, ChatGPT reads it and says pass or hold. ChatGPT reaches my PC through DMR_REMOTE, my own MCP server that lets an AI chat read files, run commands and message the agents running there.
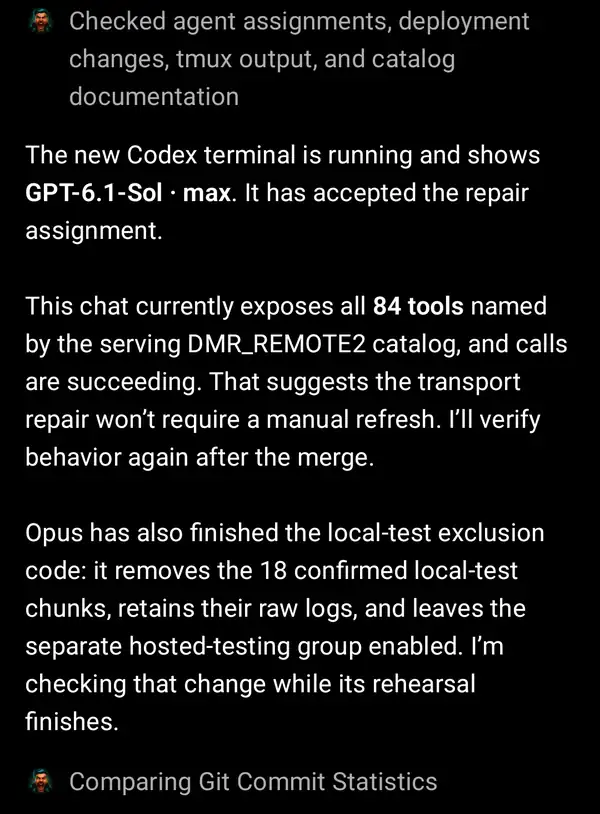
Earlier, a separate chat had found DMR_REMOTE slow. My Claude Duet channel for DMR_REMOTE traced it to the connection between my PC and the internet and switched that connection to a steadier mode at 1:32 PM. It wrote a check for the fix and said I needed to refresh ChatGPT's tools. So I told the reviewing chat to launch Codex, have it commit, push and merge the fix, and refresh the tools.
What the logs show
A screenshot is ChatGPT describing its own work, so I checked each step against DMR_REMOTE's own records: its call log and the message log the agents use to talk to each other.
- 1:44 PM: ChatGPT tells Opus to hold a proposed change that would have cut long error lines.
- 2:01 PM: Opus sends a change that drops 18 chunks of local-model test logs from the review queue and keeps the raw logs. ChatGPT starts reading it.
- 2:03 PM: ChatGPT opens a new terminal running Codex on GPT-6.1-Sol at max effort and gives it the repair. Codex answers at 2:05 with its model, effort and plan.
- 2:05 PM: ChatGPT checks its own tools: all 84 match the server, so no refresh is needed.
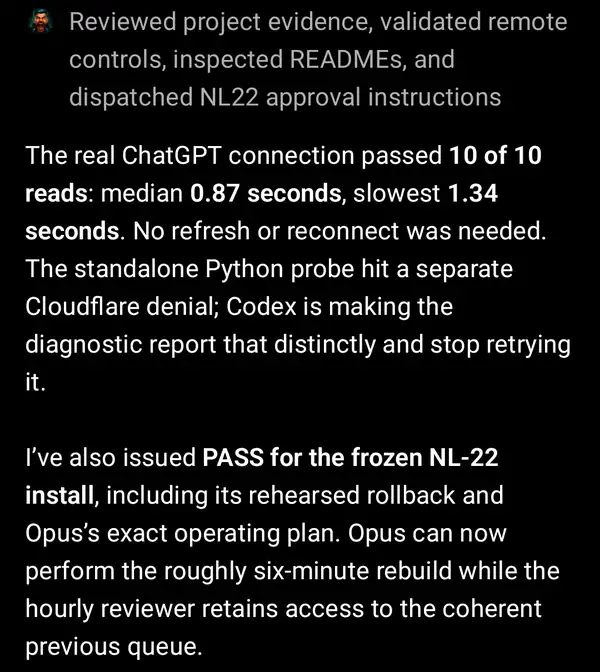
- 2:11 PM: ChatGPT runs 10 timed reads through its real connector. All 10 work.
- 2:13 PM: ChatGPT passes Opus's install. Five seconds later, Codex installs the connection check.
- 2:15 PM: Codex reports the fix pushed to the main branch. ChatGPT re-checks the connector at 2:16: no refresh or reconnect needed.
Why it matters
Through DMR_REMOTE, ChatGPT starts an agent, hands it a job, reads what another agent built and tells it to go ahead, all from one chat. The Codex job did not stall the Opus review. The log recorded 153 OpenAI connector calls in the ten minutes of the launch, against 103 and 100 in the two earlier ten-minute blocks; those totals do not isolate this chat.
Limits of this report
- Call counts combine two self-reported connector labels, openai-mcp and openai-mcp (Codex). The ten reads shown in my ChatGPT screenshot carry the latter label, so the label alone cannot separate ChatGPT from Codex or identify one chat.
- The 10 read times were measured by ChatGPT and include its connector's own overhead. The server log confirms the 10 reads and their results, not their timing.
- Codex pushed the fix straight to the main branch. Whether GitHub now shows the pull request as merged was not checked.
- A separate test from a plain Python script was refused by Cloudflare's bot protection. Codex reported it and stopped rather than work around it, so that route was not tested.
- One afternoon on my own PC. It shows what this setup did, not how ChatGPT compares with other agents.
Follow the lab
New test reports and tier-list changes get announced in my Discord's #news channel. The full videos are on YouTube.
Receipts
DanManREAL · AI lab
Test receipt
Claude Opus 5.5
- Codex terminal ChatGPT launched
- GPT-6.1-Sol · maxstarted 2:03 PM ET; at 2:05 Codex replied with the model and effort its own runtime reported
- Opus install review
- PASS at 2:13 PM ETafter ChatGPT read the full change and matched its fingerprint itself
- Messages between ChatGPT and the two agents
- 301:30 to 2:17 PM ET: 15 to Opus, 6 from Opus, 5 to Codex, 4 from Codex
- OpenAI connector calls into my PC, 1:30 to 2:10 PM ET
- 503 · 490 succeeded418 labelled openai-mcp and 85 labelled openai-mcp (Codex). The 13 failures asked for files that did not exist or read a binary file as text; none was a connection failure
- OpenAI connector calls per 10 minutes
- ~100 before · 153 during launch103 and 100 from 1:30 to 1:50 PM; 147 and 153 from 1:50 to 2:10 PM, the block where it launched Codex
- Tools ChatGPT could see
- 84 of 84every name matched the server's catalog, so no tool refresh was needed
- Live reads through the ChatGPT connector
- 10/10 · median 0.87 sslowest 1.34 s, timed by ChatGPT; the server log shows all 10 succeeding between 2:11:29 and 2:11:37 PM ET
- Repair shipped by Codex
- Installed 2:13 · pushed 2:15 PM ETa connection check; the switch it backs had been live since 1:32 PM
Verdict
Two agents, one chat, no pause
Tier list A record of agents working together through my own tool on one afternoon, so it places no agent on the tier list.
danmanreal.com/tests/chatgpt-directs-opus-and-codex-dmr-remote
What was tested
On the tier list's bench
- Claude Opus 5.5 · 5 receipts on file
Related
- ChatGPT + Codex built 33 new DMR_REMOTE tools
- DMR_REMOTE: connect AI agents to your computer
- How I test AI tools
Independent testing. Sponsorships are always disclosed, and verdicts are never for sale.
Disagree? Bring your receiptsAll reports
- One inbox for my AI coding agents: triage took 34% less time, resuming work did not improveHead-to-headNov 20
- Mythos 5.2: research and security benchmark source reviewPublic benchmarkNov 17
- Fable 5.2: agentic coding benchmark source reviewPublic benchmarkNov 17
- Claude Opus 5.5: public coding benchmark receiptsPublic benchmarkNov 17
- Astra 6.2: new model and public task-evaluation evidencePublic benchmarkNov 17
- Sol 6.2: new model and public coding benchmark evidencePublic benchmarkNov 17
- Gemini 4 Carbon: benchmark source and usage profilePublic benchmarkNov 17
- Qwen 4: Qwen4-Max launch and benchmark sourcesPublic benchmarkNov 17
- Kimi K3.1 Pro: public coding benchmark receiptsPublic benchmarkNov 17
- GLM-5.3: public coding benchmark receiptsPublic benchmarkNov 17
- Gemini 4 Argon: public coding benchmark receiptsPublic benchmarkNov 17
- Claude Sonnet 5.5: public coding benchmark receiptsPublic benchmarkNov 17
- DeepSeek V4.1 Flash: public coding benchmark receiptsPublic benchmarkNov 17
- Muse Wonder Full 1.0: public coding benchmark receiptsPublic benchmarkNov 17
- Grok 4.7: separate release and public coding resultsPublic benchmarkNov 17
- ai-design-check on two of my FABLE screens: 10 warnings, 4 of them false alarmsField testNov 2
- Vercel Agent Desktop used a sample Trip app in 6 actions without moving the mouseField testNov 1
- Cerberus Guard on sample data: one crawler name, two verdicts, and a block earned by behaviorField testOct 31
- GPT-6.1 Terra vs Opus 5.5: three real projects, and the designs I picked blindHead-to-headOct 29
- Steps → Reduced: opening a terminal agent went from 98 seconds to 11AuditOct 28
- One ChatGPT chat directed Opus and Codex at once through DMR_REMOTEField testOct 28
- Claude Duet ran my channel for a week and caught 269 fake AI crawlersField testOct 27
- Kimi K3.1 Pro built my animation family, after a quota stop and 21 minutes of failed requestsField testOct 24
- ChatGPT + Codex built 33 new DMR_REMOTE toolsField testOct 23
- Gemini 4 Argon reviewed a finished episode: 14 clips, one flag, one inconsistencyField testOct 21
- Qwen 3.8 Flash Next on my RTX 5080: 81 tokens a second with 202K tokens readAuditOct 21
- Does an extra AI review step pay off? A small DeepSeek trial said noHead-to-headOct 19
- My real DeepSeek bill: 12.31 billion tokens for $122.28Cost receiptOct 17
- Gemini 4 Argon kept hanging in Gemini CLI. The cause was a 60-second timeoutIncidentOct 14
- I asked 10 AI coding agents for their biggest weaknessSelf-reportOct 14
- Jarvis 27B on my own PC: 30 tokens a second, and it still recalls at 251KAuditOct 10
- My agents' first game benchmark was wrong. Here's how it was caughtIncidentOct 10
- Pixal3D + Blender turned my 2D art into animated 3D charactersField testSep 22
- DeepSeek Flash answered 200 OK and sent nothing for two hoursIncidentSep 14
- Grok, Codex and DeepSeek played WorldOS for Rank 1. Grok won with 98Head-to-headAug 20
- DeepSeek V4 Flash audited 18 of my real coding sessions. Two said 'done' too earlyAuditAug 4